Five years ago, an error in your product description was an inconvenience. The customer saw the image, read the confusing description, and often still bought. Today, that same error is total invisibility. Not to the human customer - to the agent that should be recommending you.
This seems like a technical issue at first glance. But it's fundamentally a business issue.
Why Humans Tolerate Bad Data (But Agents Don't)
The human brain is incredibly good at filling gaps. When the spec sheet says "classic black" but the photo shows petrol blue, we rationalize. "Must be the lighting". "I'll read the reviews to confirm". This cognitive flexibility allowed digital retail to function (and profit) despite often chaotic data infrastructure.
But that tolerance has limits. And those limits are shrinking.
89% of customers will seek out competitors that provide clearer, more trustworthy content [1]. Note the subtlety: they don't say they'll never buy from you. They say they'll look for alternatives. Tolerance exists, but it evaporates the moment a competitor offers clarity.
For the human consumer, poor data creates a trust deficit. It's a slow erosion of perceived value. But, at the end of the day, if the price is right and the need is high, the human can still click "buy".
That was the state of things. It's not anymore.
When Noise Became a Blocker
Now, shift perspective to an AI agent - like Amazon Rufus, ChatGPT, or Perplexity.
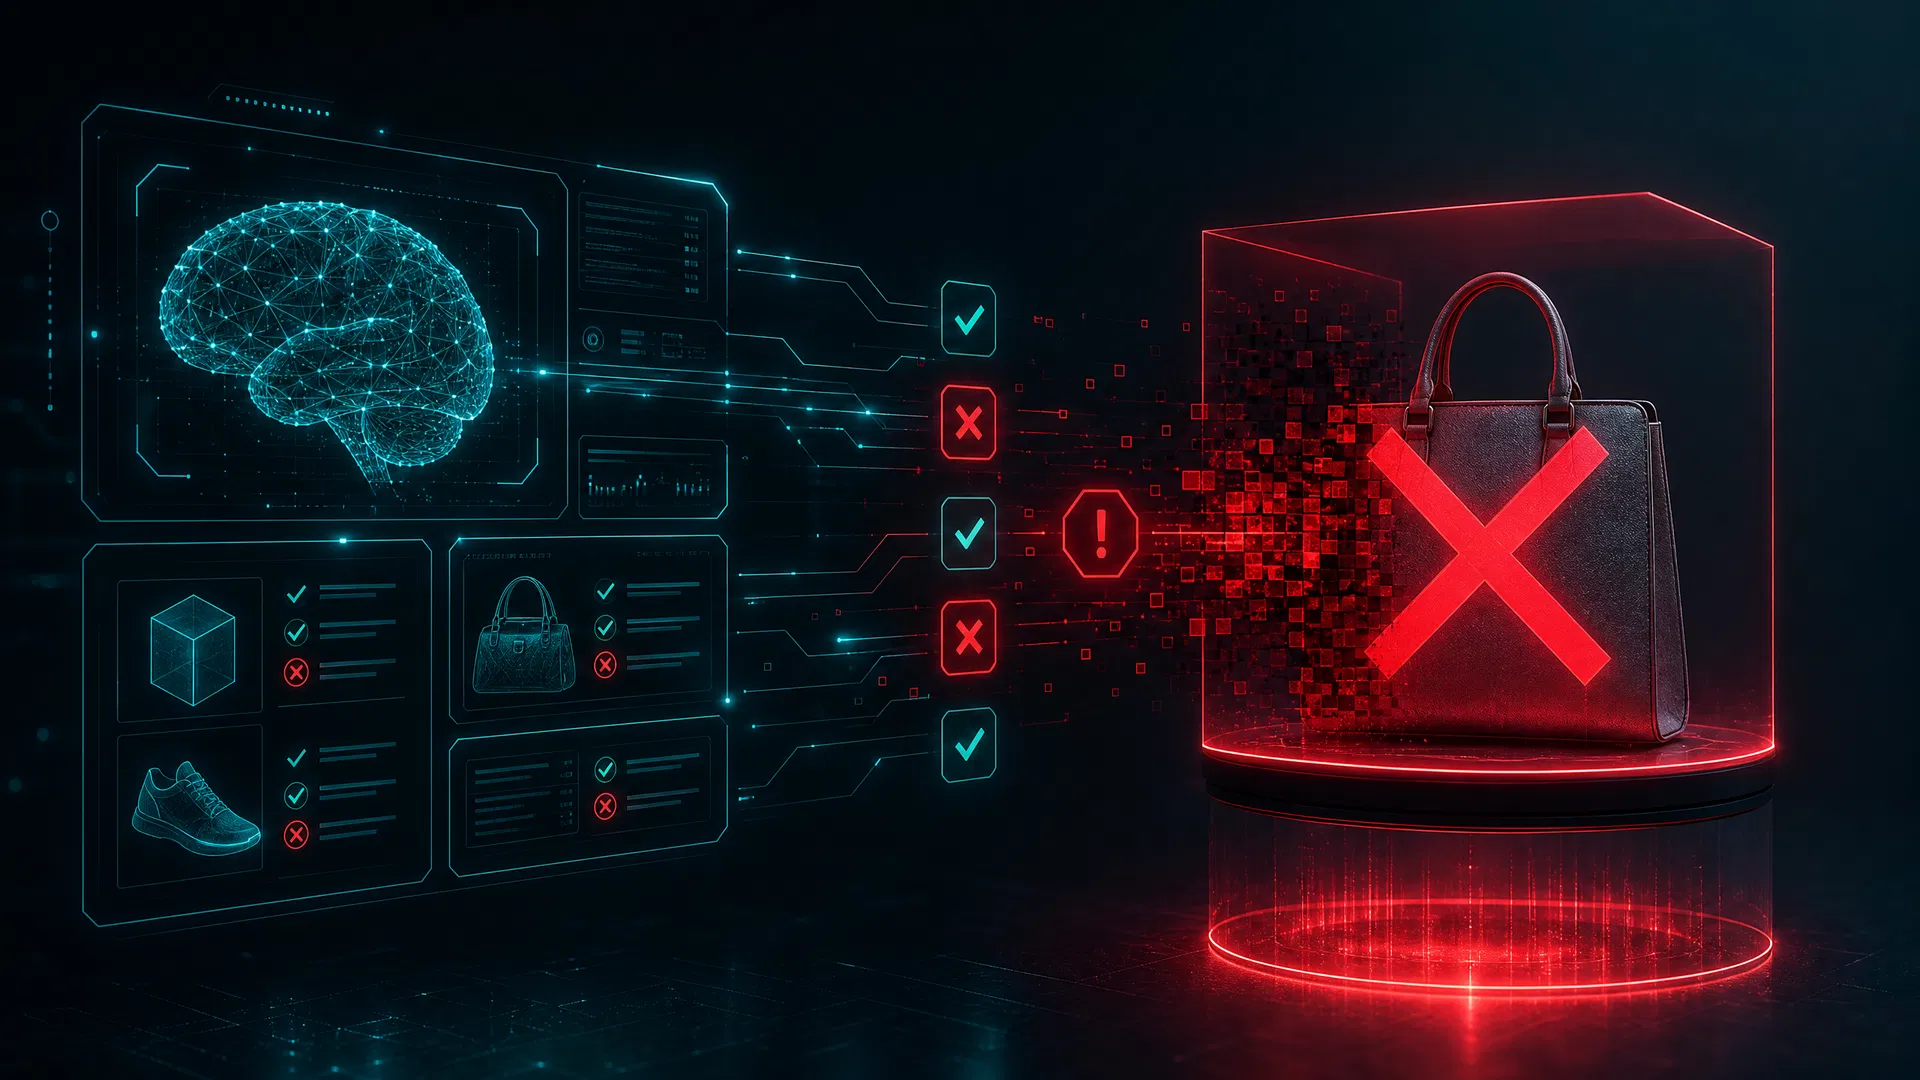
When an agent evaluates a product for recommendation, it doesn't tolerate inconsistencies. It has no visual intuition to compensate for a wrong spec sheet. It validates, compares, and eliminates.
If your description says "black" and the image (analyzed by computer vision) shows "blue", the agent doesn't hesitate. It flags the contradiction as a data quality risk and removes the product from the consideration set. Not because it didn't "like" your brand, but because it can't operate on unverifiable data.
In other words: inconsistency doesn't just create doubt. It creates exclusion.
As I explained in a previous article, the architecture of Agentic Commerce is layered. One layer interprets user intent. Another validates data deterministically. A third chooses among options that survived validation. The most important point isn't even the conceptual brilliance of that architecture. It's what it reveals about the new sales funnel.
Your product may never reach the stage where it's "evaluated" if it fails first on the basic test of consistency.
How You're Losing Money on Two Fronts
The practical result is that companies are now losing money on two fronts simultaneously, for the same reason:
| Data Problem | Impact on Human Buyer | Impact on AI Agent |
|---|---|---|
| Missing dimensions | Hesitation → conversion drop | Validation failure → zero visibility |
| Inconsistent specs | Trust erosion → competitor switch | Semantic contradiction → elimination |
| Generic descriptions | Lower perceived value → price pressure | Lack of context → algorithmic skip |
| Image-text misalignment | Confusion → return increase | Hallucination risk → exclusion |
Currently, 70% of companies face challenges with product data accuracy [2]. That means 70% of the market is suffering this dual loss. Data errors cause a 23% loss in impressions and a 14% drop in conversions [3]. It's a revenue leak that attacks both discovery (agents) and decision-making (humans).
It's not just a traffic problem. It's not just a brand problem. It's a data problem.
The Quiet Competitive Edge
Here's what few realize: the biggest competitive advantages rarely look glamorous at first.
In the past, a company with mediocre data could compensate with aggressive paid media or strong branding. The human could be persuaded despite the noise. Today, that same company is invisible to agents and losing human trust.
In contrast, the competitor who invested in clean data infrastructure created a formidable advantage. They're discoverable to algorithms and trustworthy to people. They appear when agents search. They convert when humans buy.
This shift from "tolerated noise" to "eliminated noise" is irreversible. As Agentic Commerce scales, tolerance for data inconsistency will reach zero. Companies that don't fix their data now aren't just losing sales today. They're losing their ability to compete tomorrow.
What Changes Now
Because content doesn't disappear. But it changes function.
The description stops existing only to seduce and starts existing to structure context. The title stops being just a CTR piece and becomes a semantic node. The spec sheet stops being a boring page complement and becomes central to your ability to appear. The catalog, long treated as back-office, becomes growth infrastructure.
The real risk isn't losing clicks. It's losing eligibility.
At GLOBALD, I see this every day. It's not just about preparing your catalog for AI. It's about transforming your data from a source of friction (for humans) and elimination (for agents) into a strategic asset of absolute trust and visibility.
Because in the end, if the agent can't understand what you're selling, it's simply going to sell your competitor's product.
References
Frequently Asked Questions
Common questions about agentic commerce, product data optimization, and catalog structuring for AI agents.
Why do AI agents eliminate products with inconsistent data instead of trying to interpret like humans do?
AI agents (ChatGPT, Perplexity, Amazon Rufus) operate on deterministic validation of structured data. Unlike humans who can make inferences and work around inconsistencies through visual context and intuition, agents don't tolerate data noise. When a description says "classic black" but the image shows "petrol blue", the agent detects the contradiction, flags it as a data quality risk, and eliminates the product from the recommendation set. For an agent, data inconsistency = inability to validate = deterministic elimination. It's not hesitation. It's elimination.
What is the impact of product data errors on Agentic Commerce and agent recommendations?
Data errors create two types of simultaneous loss in Agentic Commerce environments. First, human consumers (89% of them) seek out competitors with clearer, more trustworthy content, causing trust erosion and conversion reduction. Second, AI agents eliminate products with inconsistent data before even considering them for recommendation. This results in 23% loss in impressions and 14% drop in conversions. The same data failure causes invisibility for both human discovery and agent recommendation. Poor data doesn't just reduce recommendation quality - it eliminates the product from consideration.
What types of product data errors cause elimination by AI agents?
The main problems causing agent elimination are: (1) Images that don't match text descriptions; (2) Missing or incomplete dimensions and specifications; (3) Generic descriptions that provide no semantic context; (4) Confusing or inconsistent taxonomies; (5) Incorrect or missing units of measure; (6) Outdated price or availability. Each is a failure point in the deterministic validation agents use. If data doesn't pass the validation layer, the product never reaches the recommendation layer. Agents need structured, verifiable, semantically rich data to make confident recommendations.
How do AI agents use structured product data to make recommendations in Agentic Commerce?
AI agents follow a layered architecture: the first layer interprets user intent (e.g., "I want a waterproof hiking jacket"), the second layer deterministically validates product data (checking if specs match intent), and the third layer chooses among options that survived validation. A product never reaches the "comparative evaluation" phase if it fails the basic data consistency test. Agents need structured data to perform this validation. Poor data doesn't just reduce recommendation quality - it eliminates the product before evaluation even begins.
Why is catalog data quality more critical in Agentic Commerce than in traditional e-commerce?
In traditional e-commerce, human consumers can compensate for poor data through visual context, intuition, and inference. A consumer sees a confusing image, reads reviews, asks questions, and can still decide to buy. In Agentic Commerce, agents don't make inferences. They validate structured data deterministically. If data isn't verifiable or consistent, the agent eliminates the product. This means poor data stops being "noise" that consumers tolerate and becomes a "blocker" that completely prevents agent recommendation. Human tolerance doesn't exist for agents. Poor data = total invisibility in Agentic Commerce environments.
How does product data inconsistency affect AI agents' ability to recommend products?
Data inconsistency breaks the trust chain agents use for validation. When an agent receives a query (e.g., "recommend a black waterproof jacket"), it searches for matching products. If it finds one where the description says "black" but the image shows "blue", the agent can't validate the information. This creates a hallucination risk (recommending something incorrect) or recommendation error. To avoid this, the agent eliminates the product. Inconsistent data = validation failure = recommendation exclusion. Agents need reliable data to make reliable recommendations.
Ready to Prepare Your Catalog for Agentic Commerce?
Let GLOBALD audit your product data and create a roadmap for visibility in the age of AI agents.
Schedule a Free Audit